The VDI (Verein Deutscher Ingenieure) publishes in the VDI 3601 Warehouse Management Systems specification, a complete list of requirements to modern WMS software systems including quantity- and location-management as well as transportation management and disposition. These requirement topics are listed below with a short description how it is realised in OpenWMS.org.
Administratives environment
User and authorisation management (VDI3603-5.1)
OpenWMS provides a service that is capable to manage Users, Roles and Permissions. Event client devices that need to authenticate with the system are managed within this service. Entry points into the system are either user interfaces (web/mobile), machinery controllers (PLC/IPC) or 3rd-party software systems that interact via arbitrary interfaces with OpenWMS. All are connected via different channels (Omnichannel) where each channel needs to be protected against unauthorised access. The OpenWMS UAA service and OpenWMS API Gateway service take a central role in here.
Gaps:
Achievement rate:
Permissions is slightly handled differently in OpenWMS here. The permission itself defines the visibility
Access Control Lists (ACL) data security on row level is not implemented and would violate the overall performance of the system. This is handled with authorisation on UI and service access
Multiple languages (VDI3603-5.2)
Supporting i18n and l10n is an essential feature of every user interface application in OpenWMS. The existing COP (web application for administration) and BOB (mobile handheld application for operational purpose) adopt to the authenticated user language. The language setting is either taken from the user agent or can be set individually by the user itself. Expected messages coming from backend services do also take the user language into account. Unexpected messages are translated in the user interface to generic ones.
Gaps:
Achievement rate:
Master data records are not multilingual. For example, if the product description is only stored ones. If this needs to be translated then a translation service on client (UI) side must be used
Locations and LocationGroups aren't aware of particular language settings for printers
Parameters (VDI3603-5.3)
The OpenWMS application landscape provides multiple ways to store application parameters. Technical parameters are usually stored at a central place within the OpenWMS CORE Configuration Service whereas business relevant parameters are stored in the database managed by the OpenWMS CORE Preferences Service. Those parameters have validity ranges (scopes they are valid in). For example a user-scoped parameter is only valid for a single User, whereas an application-scoped parameter is valid for the whole application. Role-scoped and service-scoped parameters exist as well. Parameters changes are immediately propagated into the impacted parts of the system and take effect directly.
Gaps:
Achievement rate:
no gaps
Ergonomics (VDI3603-5.4)
Business processes as well as administrative processes require comprehensive user interfaces on suitable devices. A variety of user devices might be used in warehouse logistics. Either RF terminals, modern mobile devices with built-in capabilities for printing and scanning or desktop client PC in the control room or at operative workstations with integrated scanners and scales. It is challenging to fit all requirements across customer projects with their vast of devices, workflows and custom dialogs. OpenWMS.org comes with two user interface applications that both offer a maximum of flexibility to provide custom dialogs on arbitrary devices. One is designed for LAN-connected desktop clients, the other one for wireless connected mobile handheld devices.
Gaps:
Achievement rate:
Not all processes are realised in both applications. This must be done project specific on demand
Archiving (VDI3603-5.5)
Archiving of processed and completed data records is a central task across all system components. Because archiving can be done on several layers of the application stack, this is not an essential part of the OpenWMS.org software and implemented as private licensed components. The Enterprise Edition of OpenWMS.org contains API and services to archive processed data after a configurable duration of time.
Gaps:
Achievement rate:
no gaps
Core functions
Warehouse structure (VDI3603-6.1)
In OpenWMS.org only LocationGroups and Locations exist to model all required physical facilities of the warehouse. LocationGroups follow a tree-like structure and may have Locations attached. A warehouse (VDI term) is represented by a LocationGroup. A storage area (VDI term) might be modelled with a LocationGroup that belongs to the warehouse or as a logical grouping of storage locations (VDI term). The storage location in terms of the VDI standard is in OpenWMS.org represented as a Location that is of a LocationType (VDI: area of activity). With the general LocationGroup / Location structure almost all projects can be realised without any further customisation.
Gaps:
Achievement rate:
A Location can only be of one LocationType and not of multiple
Special types of LocationGroups or Locations might require their own attributes. Therefor it might be better to model those as dedicated entities in projects. For example a workstation could be modelled as a Workstation instead of a Location with it's particular attributes.
Master data management (VDI3603-6.2)
The logical product definition (Product) can have arbitrary attributes assigned in OpenWMS.org. A Product has a base unit it is managed or can also have a list of other units it is expected to be received. The physical representation of a Product stores the actual information about serial numbers, lot, charges and so on. Packing specifications (VDI term) refer to a Product and are handled by the OpenWMS Packing Service. Business partners (VDI term) - in all constellations - are managed by the OpenWMS Partners Service.
Gaps:
Achievement rate:
no gaps
Inventory management (VDI3603-6.3)
Inventory (physical items) can be stored directly on a Location or within a container that is used to carry the inventory (LoadUnit). Inventory is modelled with PackagingUnits and arbitrary customer specific attributes.
Gaps:
Achievement rate:
Currently there is no exposed attribute marking inventory as cut or filling. This can be handled in a customer specific field
Transport management (VDI3603-6.4)
Core functions
Incoming goods
Warehouse-internal processes
Outgoing goods
Additional functions
Batches
Cross-docking
Dock/yard management
Double/multiple-depth storage
Hazardous material
Hazardous substances
Weight control
Handling units management
Kit building
Consignment
Empties and load carriers
(Multiple) client capability
Multi-warehouse handling capability
Best before dates
Package optimisation
Production supply and removal
Resource planning/labour management
Returns
Serial numbers
Slotting and warehouse reorganisation
Forklift guidance system
Value added services
Vendor managed inventory
Scrapping
Customs
In OpenWMS.org each business function is represented by one or more business services. Almost always it is a 1:1 mapping where a business function is implemented by one single business service - a software building block. Every software component is part of one the four domains: WMS, TMS, COMMON or CORE.
Stores technical application parameters at one place. It reads those configurations from a local filesystem or from a remote Git repository. This has the advantage that all configuration changes are tracked and audited. Beside technical configuration any kind of parameters can be handled. The Configuration Service provides the technical configuration to all other services. Changes are directly propagated to the affected services and do not require a restart of those. This increases maintainability and availability.
Stores parameters in a relational database. Those parameters are the nature of business relevant kind instead of technical purpose. A parameter can be specific to an user only, to a group of users (role), to a service or valid for the whole application. For example, the default language setting of an user in the user interface is stored as a user scope parameter, whereas all available languages might be stored as application parameter.
Provides an API to create documents (PDF) from a template (JasperReports) and print those documents. After creation it stores the document before sending to the printer. It offers retry mechanism and managing basic printer settings. A relational database, the filesystem or MongoDB (NoSQL) can be configured as document store.
The COP web application is a single-page application (SPA) built with Angular technology. It offers a variety of management and overview screens for the warehouse functionality.
BOB is a native application built for IOS and Android mobile devices. It offers a narrowed set of business processes for the essential warehouse functions, like goods receiving, inventory movement, picking etc.
The OpenWMS.org Common Service provides essential functionality to deal with Locations, LocationGroups and TransportUnits. For a simple example, it offers an API to move a TransportUnit from a Location A to a Location B. Besides that, also other secondary resources exist, like TransportUnitTypes or rule sets to define what type of TransportUnit can be put on what type of Location.
This kind of driver uses plain vanilla TCP/IP socket communication between PLC and WCS. Arbitrary project-specific messages structures can be used on top of the socket connection. It supports simplex and duplex communication between both partners. One single instance can connect to multiple parters.
This driver is based on the OPCUA architecture to exchange data between WCS and PLC/IPC. It supports reading from and writing to server nodes and subscriptions.
The Transactions Service captures business transactions and stores them in the database. A business transaction is some important operation that is performed as part of the warehouse processes. For example, moving inventory between locations or changing the inventory quantity.
The Common Tasks Service is used to manage human user tasks in a warehouse. These general tasks are not specific to the WMS domain and can be used very flexible whereas WMS specific tasks (as part of the WMS Tasks Service) are more specific and can cover more detailed WMS information.
This service allows to create TransportOrders in automated warehouses. A TransportOrder is used to transport TransportUnits (e.g. pallets, boxes, cartons) between warehouse locations. TransportOrders are created when a customer order is received or goods enter at the warehouse.
The TMS Routing service is used in automatic warehouses to route TransportUnits on conveyors through the warehouse. It is responsible to handle incoming messages and selects the appropriate workflow process that finally executes the handling. The workflow is a BPMN 2.0 compliant workflow, with extensions of the used workflow engine.
The purpose of the Receiving Service is to handle goods receipts. It offers an API to create incoming orders, so called Receiving Orders (expected receipts). These kind of receipts are announced before goods are received. In contrast, blind receipts are also supported. Those don't require any announcements and allow to capture goods that are not expected to receive.
Physical inventory and product definitions are managed in the Inventory Management. Plugins for putaway and allocation can be linked to this service. Putaway strategies are used to find proper warehouse locations for products. Allocation algorithms are used to allocate warehouse inventory for customer orders and manage inventory reservations.
Community version: Private Preview (Apache License v2)
The Picking Library can be linked to the Inventory Service to provide the functionality and an API for picking. Currently two picking strategies are implemented: Pick & Collect and Pick & Pack.
new module - under development. The purpose of the OpenWMS.org Partner Service is to manage all kind of partner companies, either they are in the role of a customer or a supplier or a manufacturer or any other kind.
The Shipping Service is responsible to handle outgoing orders, those leaving the warehouse. In particular these kind of orders are typically customer orders, where each order has multiple order positions. The OpenWMS.org Shipping Service creates smaller chunks of each order position - the so-called splits.
Private Preview (Apache License v2)
OpenWMS.org is a flexible and free-to-use warehouse management and material flow control system. It is flexible because it can be tailored depending on the required functionality in the actual customer project. If, for example, a warehouse management is not required, this functionality can simply be omitted. Even more fine-grained tailoring is possible. If a project does not require Picking processes, the OpenWMS.org WMS Picking Service can be omitted either. OpenWMS.org is free-to-use because the sourcecode is available as opensource under the Apache 2.0 opensource license. Hence consultancies, integrators or any other development team can download the software as source or pre-built container images, customize it for the end-customer projects need and sell it with the project.
Business Drivers & Goals
Because the software is free-to-use there is not a superficial business model for the authors. What is the business driver or goals of this project? The authors offer consulting, coaching as well as development services based on OpenWMS.org.
The driver for the authors is to make OpenWMS.org a widely used framework to build projects in the intralogistics domain with.
The business goal is to even extend this vision to make OpenWMS.org a disruptive software framework in the warehouse management and logistics software and to replace any other closed source warehouse management and material flow control software.
Requirements
The most important functional requirements of the OpenWMS.org project.
OpenWMS.org must offer a Material Flow Control (MFC) solution for automated warehouses and should also provide a base solution for manual warehouses
OpenWMS.org must provide WMS modules for the basic warehouse management processes that can be used as-is or as a base for custom implementations
The existing and upcoming functionality of OpenWMS.org is comprised by the issues tracked in GitHubs issue tracker. Notice, that most of the requirements target on particular microservices only and are therefor directly put in one microservice' issue trackers.
Quality Goals
In a nutshell
OpenWMS.org must be built flexible and customizable enough to be tailorable in every particular project to the required functionality
Building applications, solutions and projects on top of OpenWMS.org must be painful and simple as possible in order to minimize the effort in customer projects
Systems built on OpenWMS.org must behave in a consistent and reliable manner. Data loss and deadlock situations must always be prevented
In detail
An increasing list o quality goals…
Domain
Priority
Characteristic
Scenario
WMS
High
Accountability
The system must durably store who triggered when what kind of critical operation
TMS
High
Performance
Requests that drive the material flow control, in OSIP a REQ, must be answered in less than 200ms
TMS
High
Availability
Critical processes in TMS must not depend on the availability of WMS processes
General
High
Performance
Processing orders in each domain must not affect the performance the processing in other domains
General
Medium
Reliability, Maintainability
Software changes must be applied within zero downtime of the whole system and may not affect unchanged parts of the system in terms of availability
General
Medium
Portability
The system must not depend on any runtime platform to make it portable across different runtime environments
General
Medium
Installability, Performance
Solutions built on top of OpenWMS.org can be split into parts that run on different platforms. Some parts may require to run close to hardware in order to fulfill performance requirements
General
Low
Extendability
The system must be built in order to be highly extendable in customer projects
Business Context
The OpenWMS.org system consists of warehouse management and material flow control components. It is embedded into an ecosystem with a typical enterprise resource planning system, field controllers, manufacturing control systems and other counterparts that exist in the area of eCommerce and intralogistics warehousing.
Figure 1. Business Context
Component
Description
ERP
The enterprise resource planning system is in this context responsible to serve OpenWMS.org with any kind of logistic orders, like orders for Picking, Shipping, Receiving etc
MES
The manufacturing execution system is another IT system that is connected to OpenWMS.org and is responsible to orders into production lanes in the manufacturing industry
PLC
A system of programmable logic controllers is directly connected to the TMS part of OpenWMS.org and is controlling and driving the automation hardware in warehouses
Printing System
Printer hardware could be connected directly to OpenWMS.org or via print servers to print delivery slips, tracking notes and reports
Operational UI
An user interface for human operators serves processes for Picking, Clearing, Receipts
Administration UI
An user interface for system administrators to create reports, manage orders and workplaces etc.
Technical Context
The technical context focuses on the technical details of the interfaces between OpenWMS.org and surrounding systems.
Figure 2. Technical Context
Component
Description
SCM
The Supply Chain Management module of an ERP
DB
A database with tables used to transfer data
User Interfaces
A group of all user interfaces connected to OpenWMS.org
Relationship
Name
Description
SCM-WMS
transfer tables
Tables to receive and send information between the ERP and WMS
SCM-WMS
RFC
A RFC connection over tcp/ip is used to transfer information between the ERP and WMS
SCM-WMS
webservice
A webservice connection over http is used to transfer information between the ERP and WMS
User Interfaces-WMS
REST
User interfaces communicate via REST API with OpenWMS.org services
User Interfaces-WMS
Events
User interfaces may also communicate via websockets and receive events from OpenWMS.org
MES-TMS
webservice
MES may control the TMS services via http webservices
PLC-TMS
RFC
A PLC is usually connected via RFC over tcp/ip to the TMS services
Printing System-WMS
RFC
A printing system is addressed over tcp/ip to print reports from WMS
This chapter lists all common design principles valid for all OpenWMS.org microservices. Each microservice implementation may add specific rules and principles but overall rules are captured here.
Microservice Architecture
Description
Originally coming from a more technically organized application layout, in 2016 the step was taken towards a microservice architecture. Each microservice focus on its own functional use cases, business functions and business value. The whole OpenWMS.org system encompasses around 15 different services that serve different purpose and that can be composed differently in end-customer projects.
Justification
OSGi was a great technology to built modular applications. One of the most important requirements on OpenWMS.org is the ability to extend in a flexible way and to get changes into production without downtime. The best successive architecture style after OSGi is te microservice style, it helps us to deploy changes easily and without downtime and to implement new features quickly.
Each microservice has its own set of database tables, either relational database tables or NoSQL collections/tables. Tables are differentiated by a naming pattern. Each table has a prefix that points to the owning microservice. All tables can be deployed into a single database, or in multiple databases or database schemas. This is a question of distribution and what need to be deployed where. Relationships between database tables of different microservices are forbidden.
Justification
It is absolutely fine to use one database for all the tables used in a system. It may also make sense to separate between database schemas, for example to separate WMS tables from TMS or BPMN tables. With this approach we do not get in conflict with the strict data separation enforced in microservice architecture style and still have the flexibility of different deployment forms
Addressing
Flexibility, Performance
Event-Driven Architecture (EDA)
Event-Driven Architecture (EDA) is a software design pattern where system components communicate and react to events (changes in state or significant actions) rather than making direct synchronous requests. Beside events (that express what happened in a system) there might also be commands, to express or request an action from a system component.
Nowadays there’re two major architecture categories:
Traditional messaging with an Enterprise Message Broker (eg. RabbitMQ, AmazonMQ, Azure Service Bus)
Log-based messaging with a (Distributed) Event-Streaming Platform (eg. Apache Kafka, AmazonMSK)
The most obvious difference is, that in tradtional messaging systems the message is removed from the broker as soon as it is consumed, whereas in event-streaming platforms the message can be replayed.
Architectural Styles in EDA
Basically three high-level architectural styles exist as explained in the following. The data sent between producer and consumer can be subdivided into two types: Thin events and Fat events. The former type only carries an unique data identifier and (if required) some metadata information (eg. type, date), whereas the latter is used to transfer the full data representation as part of the event.
Queue & Pub/Sub
In general in Queue and Pub/Sub architectural style it is preferred to deliver Thin events. All consumers must query the producer to get the actual data instead of getting the data delivered as part of the event.
Queue (Point-to-Point Messaging)
A queue delivers each message to only one consumer.
Characteristics
One message → One consumer
Messages removed after consumption
Good for task processing
Supports worker scaling
Order usually preserved
Example Use Cases
Background jobs
Email sending workers
Order fulfillment tasks
Pub/Sub
In pub/sub, a message is sent to all subscribed consumers. Every subscriber gets its own copy of the message
Events are stored in ordered event logs, that can be replayed by consumers repeatedly. Consumers mutate their datastores based on these events. In contract to the first architectural style, the event contains all required data (Fat event) so consumers do NOT need to call the producer subsequently.
Characteristics
Rich event payloads
Fully asynchronous
Low service coupling
Higher network usage
Faster consumer processing
Example Use Cases
Microservices architectures
High performance systems
Real-time processing
Loose coupling required
The downside of this log-based messaging systems, compared to traditional message brokers are:
Complex to setup, operate and maintain
Querying a large amount of data on the event log is not efficient, compared to a local datastore or cache
Event Sourcing
Event Sourcing is even a step further. System state is derived from the event history. Events are the source of truth and consumer' datastores are not - those can be eliminated or serve as local temporary store only. In this type of architecture the event log is seen as the “central nervous system” of the application (or even the organization) that stores all data changes over the time in the event log.
Characteristics
Events are the source of truth
Full audit trail
Supports time travel (state reconstruction)
Complex to implement
Requires strong event versioning
Example Use Cases
Audit-heavy domains
High data traceability required
Supported Services on Azure
Technical summary: Service Bus moves work. Event Hubs moves data.
Azure Service Bus
Message Broker (Queue & Pub/Sub)
Azure Event Hubs
Event Streaming Platform
Designed for
Reliable command messaging
Application integration
Transactional workflows
Request/reply patterns
Streaming ingestion
Telemetry pipelines
Analytics data feeds
Event firehose patterns
When to take
Reliable delivery
Message locking
Dead-letter queues
Transactions
Commands/tasks
Workflow messaging
Massive scale
Replayability
Analytics pipelines
Event history
Streaming ingestion
The one doesn’t replace the other. Here a direct feature comparison:
Feature
Azure Service Bus
Azure Event Hubs
Primary Purpose
Enterprise messaging
Big data event ingestion
Category
Message Broker
Event Streaming Platform
Messaging Model
Queue + Topic/Subscription
Partitioned event stream (log)
Typical Message Size
Small/medium business messages
High-volume telemetry/events
Throughput
Thousands/sec
Millions/sec
Latency
Low
Very low
Retention
Message removed after consumption
Time-based retention (1–90 days or more with Capture)
Replay Events
❌ No
✅ Yes
Ordering
FIFO via sessions
Ordering per partition
Delivery Guarantee
At-least-once, exactly-once workflows possible
At-least-once
Transactions
✅ Supported
❌ Limited
Dead Letter Queue
✅ Built-in
❌ Not native
Message Locking
✅ Yes
❌ No
Backpressure Handling
Built-in
Consumer-managed
Scaling Model
Broker-managed
Partition-based horizontal scale
Kafka Protocol Support
❌ No
✅ Yes (native Kafka API compatible)
OpenWMS.org is made up microservices that communicate between each other in a variety of protocols either in synchronous or asynchronous style. A directed synchronous communication should always happen from north to south and west to east, whereas asynchronous events, commands and messages may be interchanged in all directions to get information populated across the whole system.
Figure 3. Callgraph and informationflow between the four OpenWMS.org domains
Contained Building Blocks
Component
Responsibility
ERP
The external Enterprise Resource Planning system is the host that sends higher level warehouse orders. Not part of OpenWMS.org
WMS Domain
The Warehouse Management System is the layer that interacts with the ERP and implements all common warehouse processes, like Receiving, Shipping, Inventory, Picking etc.
TMS Domain
The Transport Management System implements the Material Flow Control (MFC) in automatic warehouses and also the processes used in manual warehouses
COMMON Domain
This layer contains all essential processes and services for every warehouse solution, no matter if automatic or manual warehouses, with or without a WMS layer. These services are always part of each customer project
CORE Domain
The CORE domain contains infrastructure components, that are not specific to warehouse projects and can also be used in other arbitrary projects. Most of these services are optional to use and depend on the deployment scenario
Subsystems
Subsystems do not belong to OpenWMS.org, but are communication partners like PLC (Programmable Logic Controllers), scale units, robots etc.
Each of the OpenWMS.org services can be assigned to one of the four domains: CORE, COMMON, TMS or WMS. A more concrete view with seven often used microservices looks like below. Notice that the information flow is visualized not the dependency graph. WMS services are not directly called from services of the COMMON or TMS domain.
Figure 4. Informationflow between 7 OpenWMS.org microservices
Component
Responsibility
COMMON Service
Manages Locations, LocationGroups, TransportUnits and other essential domain objects that exist in every warehouse solution.
The COMMON Service does not know about other surrounding services but sends out information to its outer components
TMS Service
Tracks the movement of TransportUnits with TransportOrders in automatic warehouses. The service directly uses the interfaces of the COMMON Service
COMMON Driver
This is the TCP/IP driver component used to communicate to subsystems that implements the OSIP protocol. It forwards incoming messages to a routing component, like TMS Routing in an automatic warehouse
TMS Routing
This is a routing component used in automatic warehouses where actually the material flow control logic is defined. For this it uses many API of other services indirectly
WMS Inventory
This service is responsible to manage warehouse inventory, like Products and is mainly triggered by changes in other components
WMS Receiving
Warehouse receiving processes, like receipt announcements are implemented and processed here. It consumes events from other services and directly calls API of others
WMS Shipping
Contains warehouse shipping processes that trigger movements
Lets have a closer look and look inside the microservices to see how they interact between each other. Only the asynchronous communication path is shown with the messaging components like Message Filters, Message Queues and routing information.
Figure 5. Insight of communication between the 7 OpenWMS.org microservices
Important to notice is the component who owns a shared resource. Basically queues are never shared and always kept by the service internally. But intermediary components like Routers or Filters (here RabbitMQ exchanges) need to be accessed from both communication partners, hence a clear ownership must be defined. As an example take the exchange with name common.tu.commands into account. This is owned by the COMMON Service and used as an inbox and outbox for command messages. Consumers interested in outgoing commands may subscribe a queue to this exchange to gets updates on cache evicts or to send commands to create data managed by the COMMON service. The command structure itself is also given by the COMMON service.
An OpenWMS.org microservice implementation with Java technology is structured into source packages. Some generic and often used packages exist in all microservices with a common sense. In the example below the structure underneath the common package is also applied to any other domain package like core, tms or wms.
Figure 6. Java package organisation
Beside these packages exist dozens of others specific to every microservice. The Transportation service for example has also a separation into functional packages, like transports or routes. The packages and conventions shown here should be followed for every OpenWMS.org microservice implementation when possible.
Package
Responsibility
org.openwms
Top level product package
core
All types that belong to the CORE domain
common
All types that belong to the COMMON domain
tms
All types that belong to the TMS domain
wms
All types that belong to the WMS domain
api
Types that are relevant for client applications or API consumers and that are cut off into a separate build artifact
app
Types and configuration artifacts that are responsible for the microservice lifecyle
commands
Contains all command types and handlers, processors of commands
config
Contains configuration classes responsible for the microservice external configuration, most often Spring Boot managed classes mapped to properties files
events
All event types used service internally and externally. External events must put under api.events
impl
The internal implementation details of the microservice API
Most often a warehouse management system and material flow control are installed in a datacenter close to the warehouse and the hardware, either on a single server or on multiple ones. This on-premise deployment has the advantage of increased maintainability, operability and throughput.
Simple Single Box Deployment
The simplest way to deploy OpenWMS.org is the Single Box Deployment. All software components installed on one single physical or virtual server. All processes run and communicate in-memory and do not require external network access. In its simplest way all microservices can be installed as single instances as Unix daemons or MS Windows services. Scalability and elasticity are not an option in a typical warehouse project, therefore there is no need to scale out processes on demand.
Figure 7. Simplest deployment on single server
The services could also be installed as Docker containers on Docker Compose to increase operability and reliability but this is not a requirement.
Motivation
Simple project setup
One OpenWMS.org system for one warehouse project, no need to combine other OpenWMS.org instances
Independent IT systems operated by the warehouse management team
No need to scale out, the load and frequency is known for present and for the future
Quality and/or Performance Features
High degree of latency
High level of operability
In multiple warehouse projects per site the maintainability decreases
Mapping of Building Blocks to Infrastructure
Component
Responsibility
Server
Either one physical or virtual server instance for the whole warehouse project
RabbitMQ Server
A RabbitMQ installation, running as a OS service
Virtual Host
Inside the RabbitMQ server a virtual host instance is created for the warehouse project
Database Server
A database server installation
Database Instance
A instance dedicated for the warehouse project, that contains all schemas and tables (the feature of schema is optional)
Microservice Network
A logical group of microservices. Has no
Multi Box Deployment
Similar to the one-box deployment, OpenWMS.org can also be split and deployed on multiple machines. For this scenario we propose to run the microservices within Docker containers and let the container scheduling infrastructure distribute the instances as needed. For this scenario we also propose Docker Swarm as container scheduling runtime. But if customers have other schedulers in place, like Kubernetes or OpenShift this works the same way. The main point here is, that OpenWMS.org does not require to run on Kubernetes or any PaaS solution. The basic requirements of this scenario are met with Docker Swarm.
Figure 8. Deployment distributed on multiple servers
The benefit of a container scheduler in a distributed environment is tremendous. We do not need to care about low-level infrastructure details on our own and rely on proven scheduling technologies.
Motivation
A container scheduler is already in place
A robust and more reliable setup is required, where process restarts and monitoring is required
Load can be divided to multiple servers
Processed can run at multiple instances
One part of the system (e.g. TMS) is independent on the availability of other parts
Quality and/or Performance Features
High degree of latency
High level of reliability and failure tolerance
High level of operability
Advantages with multiple warehouses in the project
A distributed system is more complex and this is a decrease of maintainability
Mapping of Building Blocks to Infrastructure
In addition to the Single Box Deployment.
Component
Responsibility
Server 1
One managed Docker Swarm node (could also be a Kubernetes node)
Server 2
A second managed Docker Swarm node (could also be a Kubernetes node)
Both Docker Swarm nodes use several ports for cluster and container management. The database and the RabbitMQ are made transparently available to both nodes and microservices on each node.
For example all services on Azure Kubernetes Services (AKS) on the Microsoft Azure Cloud:
Figure 10. Deployment distributed on-premise and cloud
Communication between microservices is essential. Likewise the communication format, the protocol, is essential and absolutely required to use a well-defined structure that both communication partners, provider and consumer, understand.
Three kind of communication formats must be considered.
Information Data
The actual transferred business payload between two services is the common case of microservice communication. The service provider is in the role of upstream service and feeds all consuming services (aka. downstream services). Hence the provider narrows the protocol and data structures that are possible for the communication. But the consumer may choose between options, like different representation formats (JSON, XML, vendor specific, etc.) or transport protocols.
Figure 11. Information Flow
The consumer is responsible to transform the received structures into it’s own internal used data structures. This often happens in a so-called ACL (Anti Corruption layer).
Context Data
Beside the actual business payload context relevant information must be transmitted as part of each microservice communication. For example this is relevant to trace calls within a call chain and particular to support operationability and monitoring of a distributed system.
This contextual data is not specific to each microservice, like information data is, but has to follow a common structure that is applied in every microservice implementation. Each microservice acts as consumer and additional as producer, respectively enricher, of context data. Finally the transferred information must be sufficient to feed external monitoring systems with.
Context data of OpenWMS microservices is transferred in headers, either HTTP headers or RabbitMQ headers.
For example: When OpenWMS.org microservices are deployed in a multi-tenant environment the tenant identifier is required with each call. This information is typical context data that needs to be transferred between client and server. For a HTTP call the tenant identifier is propagated as custom HTTP header X-Tenant and for asynchronous AQMP messages the AMQP header osip_tenant transfers this information.
Failure Data
In failure situations a microservice might not respond with self-defined information data structure but with failure or error responses. The structure and the protocol of these error responses must be consist across all microservices in order to establish communication even in case of errors. As an example: It is not an option that Service A returns an error response to Service B that cannot be processed by Service B because the protocol or format is unknown to Service B.
With OpenWMS we use Spring Boot as implementation framework. Spring Boot already comes with it’s own format like it exposes errors to API consumers. For REST API over HTTP a typical Spring Boot error response looks like this:
{"timestamp":1568208641323,"status":500,"error":"Internal Server Error","exception":"org.ameba.oauth2.InvalidTokenException","message":"JWT expired at 2019-09-11T13:30:41Z. Current time: 2019-09-11T13:43:27Z","path":"/transport-units/S000005270119225"}
This works well with Spring Boot consumers on the client side. Even clients in JavaScript can deal with this format. The problem here is, that the format is baked into and driven by Spring Boot and may change between mayor framework releases.
Therefor a RFC was initiated, the Problem Details for HTTP APIs (RFC7807). By applying this RFC to all OpenWMS microservice implementations we ensure that we align to a standardized but flexible and extendable format.
{"type":"https://api.openwms.dev/meta/v1/error/AlreadyExistsException","title":"AlreadyExistsException","status":500,"detail":"The TransportUnit with Barcode [S000005270119225] already exists and cannot be created","messageKey":"E0033","messageLanguage":"en-US","messageCategory":"ERROR","args":["S000005270119225"],"call":{"headers":{"x-span-id":"2485ec27856c56f4","x-trace-id":"1210be13194bfe5"},"uri":"https://api.openwms.dev/v1/transport-units/S000005270119225","path":"/transport-units/S000005270119225","method":"POST"}"timestamp":1568208641323,"error":"Internal Server Error","exception":"org.ameba.oauth2.InvalidTokenException","message":"JWT expired at 2019-09-11T13:30:41Z. Current time: 2019-09-11T13:43:27Z"}
In a distributed system we must ensure that failure situations across the network are handled properly without impacting the robustness nor performance of the whole system negatively. A technical error handling can often be done with libraries, like Hystrix, resilience4j, feign or others. Also Spring AMQP cares about and offers different strategies to deal with errors. But it is not always possible to handle failures in one standardized and automated way. At least, we need to decide what failure resolution strategy from one of those libraries is chosen in case of an error.
Error Handling with Asynchronous AMQP Messaging
Spring AMQP with RabbitMQ is used for the asynchronous messaging infrastructure. A publisher sends a message to an AMQP Exchange where a consumer process has connected a AMQP Queue to. A message is sent to the Exchange and published to one or more connected Queues. If a consumer fails to process the queued message there are several possibilities how to react: Re-Queue, Throw-Away or Forward.
Re-Queuing failed Messages In case of re-queueing the message is left in the queue and executed again. How often this happens and with what interval can be configured.
Throw-Away failed Messages Simply omit the error occurred and be silent could also be a consumer strategy. In this case the message is acknowledged to RabbitMQ and is gone from the queue - but without handling the message as demanded.
Forward failed Messages A consumer could also decided to forward a message it could not process to someone else or to just forward it into a message store without knowing about the consumers of that store - there might actually be no consumer. This pattern in basically called Dead-Letter Queueing and also RabbitMQ offers this technique.
The list of strategies is by for sure not complete but enough for what we need in OpenWMS.org. So here is a short comparison of these three strategies in relation to the use in OpenWMS.org:
Strategy
Advantage
Disadvantage
Re-Queueing
The message is not lost. It stays in the queue even after the consumer gets updated or restarted.
May slow down the system cause of repetition. Blocks other messages in the queue from being processed
Throw-Away
Processing other messages goes on, the queue is not blocked
The thrown away message is lost but could have been worth to know for consumers. Throwing it away may lead to data inconsistencies
Forward
Processing other messages goes on, the queue is not blocked, the message is not lost
The process of handling this kind of failed messages must be defined and handling them must be established. May lead to problems when a message sequence is expected (e.g. OSIP UPDX telegrams must be processed and acknowledged before any other telegram can take place)
So when to use what kind of strategy and what configuration to apply is often a decision specific to the use case.
Strategies to re-queue Messages
By default, Spring AMQP does not acknowledge a message to RabbitMQ that has failed to process. That means a listener is called over and over again. This behaviour can simply be stopped by throwing an org.springframework.amqp.AmqpRejectAndDontRequeueException within the application listener code like it is shown in Strategies to Throw-Away Messages.
But with Spring AMQP the handling is also configurable: How often a message is re-queued and the repeat interval with many other options. …
A typical Spring AMQP RabbitTemplate configuration of a service looks like:
Use Cases This is often done in use cases where the consumer expects the message is going to be repeated by the sender after a period of time.
Strategies to Throw-Away Messages
Use Cases For sure we can throw away messages, silently acknowledge them, where we know the publisher expects no answer and repeats the message in case no answer is returned. So we depend on the frequency of the publisher how often the message is repeated. For example, the publisher may be a PLC that is configured to resend the initial message request every 150 milliseconds. In this case, this could have an impact on the overall performance. Whereas an PLC may also be configured to repeat the message only after e.g. 30 seconds what has not that much impact on performance.
Configuration A typical message listener consuming the message and throws it away on any exceptions looks like this:
The listener delegates to a message handler that is responsible to execute the business logic. In case of any errors the listener throws an AmqpRejectAndDontRequeueException to signal the Spring AMQP runtime to reject the message. So it is not processed anymore.
Strategies to Forward Messages
[D10] Support of Java8 Optional in API methods
The use of java.util.Optional within API methods makes it easy to translate 404-Not Found into Optional.empty(). Without this pretty cool Spring & Jackson feature we must live with an null response object, that you might have seen at some point. Not the instance is null, but all fields of the instance are, because the sender (a Spring Boot app) sends a JSON response with http status == 404 but passes a ResponseBody, and that one is tried to be deserialised into a business object, therefor all fields of the business object are null.
[D9] Maven Dependency Declaration & Usage
Apache Maven build tool knows about a dependencies section and a dependencyManagement section.
Rule We declare dependencies with their version and classifiers but without scope within the dependencyManagement section and actually define the usage of the dependency within the dependencies section without the version but with the proper scope. It is not allowed to declare and define the usage in the dependencies section only.
[D8] Explicit database columns
Issue As we do with JSON properties in [D2] Use JsonProperty explicit we should also be explicit and name every database column. Without doing so we could run into trouble when we refactor field names but don’t want the columns to be renamed.
Rule Instead of ending with a mix of annotated and un-annotated fields, all the fields that are going to be mapped onto database columns, need to be annotated with @Column and a name must be set. The name must have the prefix C_ assigned. This is very handy to avoid cases where the Java names clashes with database keywords. For example: One could name a field user that ends in a column USER that is a keyword in RDBMS and forbidden to use. To avoid such clashes all columns have the C_ prefix.
[D7] Define a Logger
Issue To simply define a Logger instance just use a static definition and don’t add some magic third party library like Project Lombok.
This is simple, added fast and just uses Java and the logging library of choice. This line of code can be created with an IntelliJ live template dlog (define logger).
Convention - Always use slf4j as log API - Logger instances must be private to the class and static - Logger instances in OpenWMS.org code must be named as LOGGER
[D6] Direction of mapping between models
Issue In OpenWMS.org we have at least two or more domain models that needs to be mapped from one into the other. The inner business domain model of a microservice is often also the persistence model and thats fine. But outer public API have their own representation, i.e. domain model, like the VO model of the presentation of the MO model of the messaging layer. We could map in bidirectional way that makes often sense but sometime it only make sense to make in one direction.
Problem Our mapping library support the configuration of the mapping direction on attribute level but only with two options: bi-directional or one-way. The latter means from source (class-a) to destination (class-b). A explicit switch, like a-b or b-a does not exist.
Solution So we define that we always name the inner model as class-a and the outer model as class-b. By this convention it is clearly defined that we map between the rich domain model to the more simple domain model without object-graph resolution, just by traversing the source object and dereference the attribute of the destination class.
Example Here an correct example of a mapping from the inner class to the outer class:
Unique constraints start with UC, then the abbreviation for the hosting table and an identifier. Foreign keys start with FK, then the abbreviation for the hosting table and the referenced table/column.
In case of refactoring the table name change can be done at one single place. In native queries the constant can be referenced instead of a String.
[D2] Use JsonProperty explicit
In classes serialized as JSON use @JsonProperty on properties explicitly. This ensures that refactoring and renaming the fields keeps the JSON names and the API stable.
[D1] Exception translation in REST Controller
Issue Java Exceptions should be translated into proper representations at the system boundary. @RestController and @Controller classes must translate exceptions into proper JSON structures (XML is not in focus).
Solution In order to implement Spring @ExceptionHandler or ControllerAdvice in every controller take advantage of a set of those by extending the class org.openwms.core.http.AbstractWebController. Own exception classes and those of the ameba-lib library are translated properly.
[R2] Technical Service Logging (TSL)
Issue To find performance and throughput bottlenecks it is a good start to measure the time execution of methods and persist this information so it can be monitored over time.
Solution This kind of logging is addressed with Technical Service Logging (TSL). A particular log appender is used to capture the MEASURED logs and forward to a dedicated logfile with the file extension .tslog.
TSL can be turned on by setting the log level of the MEASURED category to INFO or higher. The logs must be send to a predefined appender with name TSL:
Problem Incoming http requests with URL parameters or request body data aren’t encoded correctly - even the request is decoded right. For example a request parameter that is decoded to %E6%8C could be encoded to æŒ but not to the expected String.
Solution By default, Tomcat uses ISO-8859-1 character encoding. The HTTP Connector in Tomcat’s server configuration must be configured to set the URL encoding to UTF-8. Open the server’s server.xml, search for the http connector and add the attribute "URIEncoding" as follows:
This Developer Guide contains best practises and rules useful to know when developing applications, services and projects with OpenWMS.org. It is written in a notebook style, extended during development and does not claim to be complete or even finished.
Target Audience
The guide is written for developers that are maintaining, extending or studying the OpenWMS.org codebase or build own services on top of the codebase.
A progressive fragmentation of client devices and the evolution of API driven by new product features is the driver for a proper API lifecycle management. Consumers may not adopt to API changes that quickly and stick on a particular API as long as possible or manage an upgrade as part of their own application lifecycle.
Client applications of OpenWMS.org API are not fragmented in that degree we see the fragmentation with mobile devices but also in projects of the logistics domain we deal with arbitrary devices across varying customers. In addition to that software in production is updated rarely.
One approach to deal with these challenges is to always be backward compatible and never break existing API consumer code. Stripe.com does an excellent job in API cultivation & care and explains how this could work in a fantastic blog article. Nevertheless managing and taking care of many clients is complex and may blow up the API.
Another much more simpler and often used approach is to version the API in that the URI to an API resource contains (or is tagged with) a version identifier (e.g. v1). Precisely two URI that contain a different version identifier are not the same and do not point to the same resource.
Responsibility
If we decide to version our API resources and introduce a version identifier as part of the URI, we also need to question who takes responsibility of managing the API lifecycle for each microservice. Does the development team decide when breaking changes are introduced and a new version of an API is raised? Or does an overall product management coordinate and manage major API changes and defined the public product API?
Like often the answer is: It depends. For OpenWMS.org microservice API, the development team is responsible for the API lifecycle whereas a manager role focuses, manages and communicates the public API to particular parties. Several public exposed API may exist in an omni-channel architecture where each API is a composition or a new formation of existing microservice API. In this case, a management role is in charge to communicate upcoming changes and consider client requirements and feedback.
Lifecycle
In general, the team that maintains a microservice is responsible for the API management of that service. But some overall principles exist that should be followed across all microservice API.
Maintain at least two active API versions. The newer version is the preferred version to use and the target for migration. The older version may be flagged as deprecated
Always strive for API evolution and avoid breaking changes. This is a trade-off and must be in balance with cost, efficiency and simplicity
A version identifier can be introduced in at least two different ways. Popular approaches have the version identifier as part of the query path or as separate HTTP header argument (constraint: REST over http).
Version in Query Path or Authority
The version identifier is either part of the HTTP query path or the authority.
For microservice API we prefer to use the version identifier as part of the query path
The version identifier starts with a 'v' character followed by an integer starting with 1
This is more convenient for a system of microservices that does not depend on hostnames nor authorities. The identifier as part of the query path determines the corresponding resource no matter where the service is hosted on.
OpenWMS.orgmicroservices have the API version identifier as part of the HTTP query path, as a prefix to the primary resource identifier
For public API, or those with a product character (AaaP - API as a Product), the version may be introduced as part of the authority. In particular for API that are built as product and for the purpose of different channels this is often used. The diagram below shows one part of the current OpenWMS.org API.
Version encoded in Accept Header
In contrast to use a fixed version identifier as part of the URI it is also possible to encode the version or respectively the representation type within the HTTP Accept Header. A client requests the server for a specific resource in a particular representation format. That means the same URI could be requested with different representation formats to get different representations of the same resource.
In this example a Client asks for a representation of a TransportUnit of type application/vnd.openwms.transport-unit-v1+json. The server knows this format and sends back a JSON representation of that particular version.
A valid custom representation format has the following naming pattern:
The approach to encode the requested version into the Accept header is rather the exceptional case and is only used in API that match the same query path but different representation formats are supported.
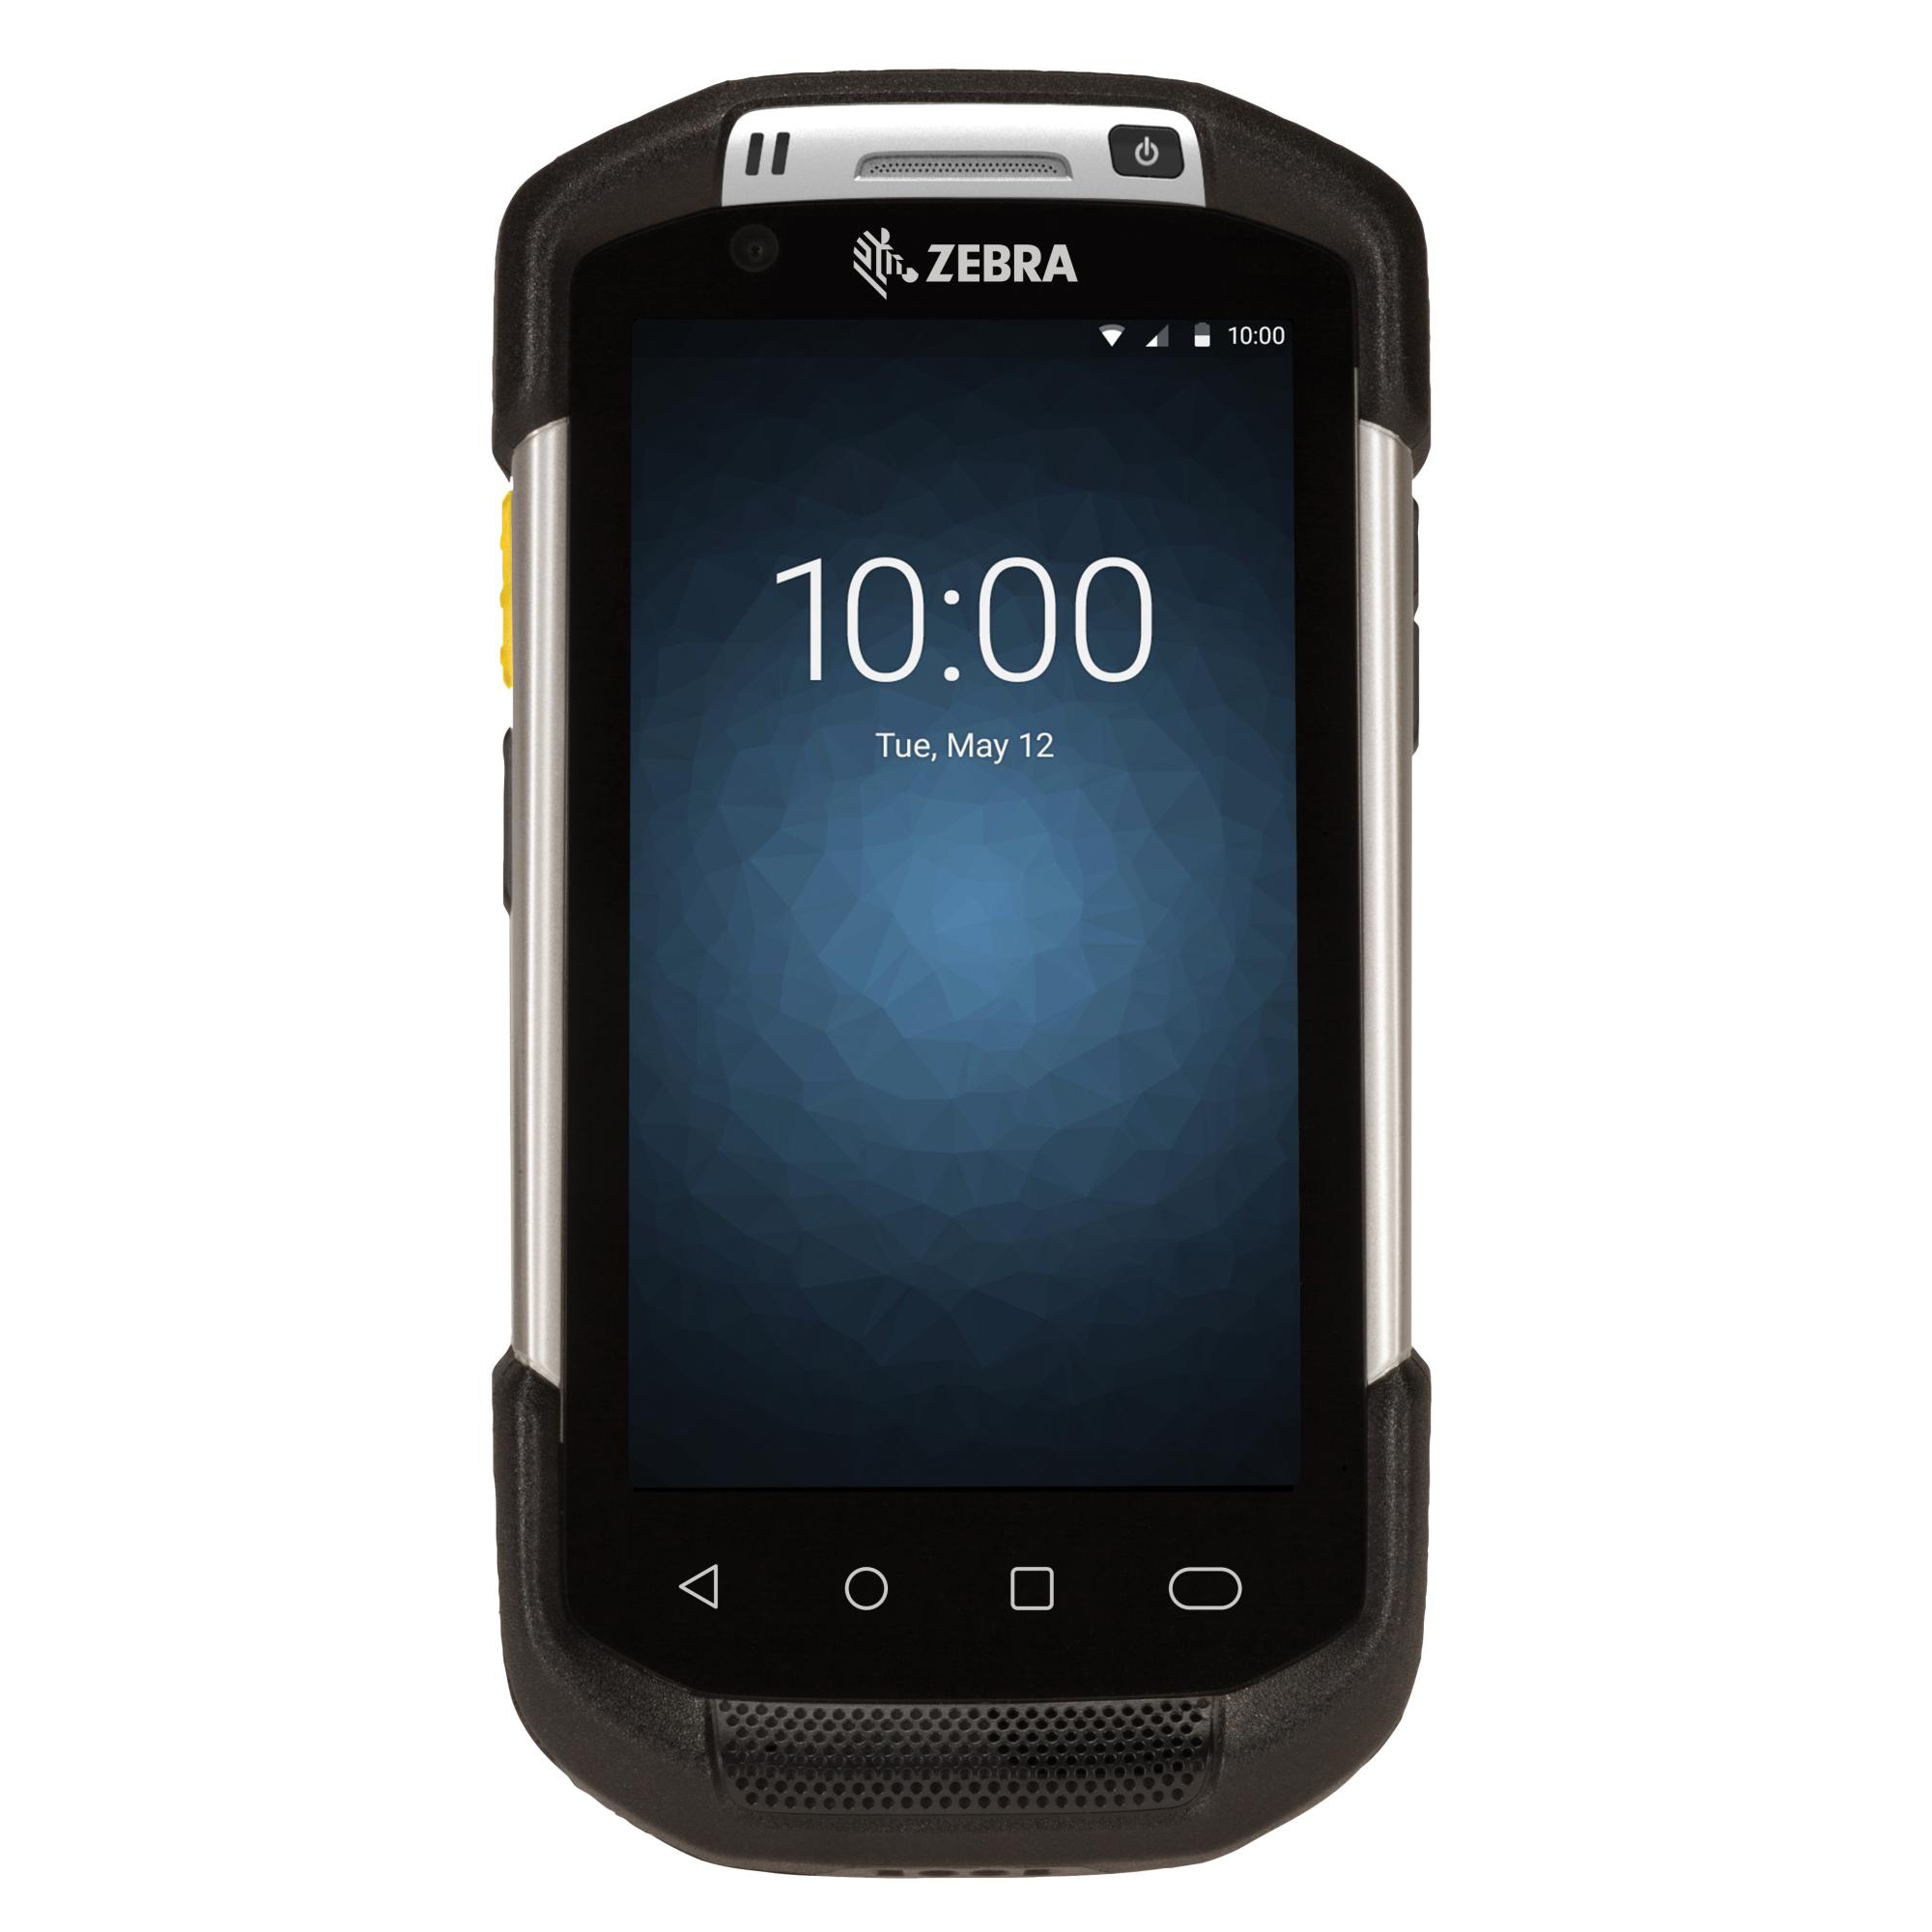
4.3" WVGA color display, Capacity Touch supports bare/wet/gloved finger and stylus inputs, Corning Gorilla Glass
Keypad
28-Key Numeric, 38-Key Numeric/Function keypads, 52-Key Alphanumeric keypads, Terminal Emulation keypads (TN5250, TN3270 and VT) , with LED backlight
Size
216 mm x 80 mm x 30 mm
Weight
400 g (3000 mAh) / 445 g (6000 mAh), with 2D imager 435 g (3000 mAh) / 480 g (6000 mAh), with Extended-Range 2D imager Cold Storage: 485 g, with 2D imager/ 520 g, with Extended-Range 2D imager
Operating Temperature
Standard: -20°C to 50°C / -4°F to 122°F Cold Storage: -30°C to 50°C/-22°F to 122°F
Impact resistance
IP65 / 1000 (1 m) Tumbles Standard: 1.8 m / 2.4 m with Rubber Boot, multiple drops onto concrete (MIL-STD-810G), crossing operating temperature Cold Storage: 1.5 m multiple drops onto concrete (MIL-STD-810G), crossing operating temperature down to -30 degrees Celsius
The native mobile application is build for Android and IOS devices.